One Text, One Visual
Turn a method into a mobile-friendly diagram
One Text, One Visual
Turn a method into a mobile-friendly diagram
Showcase
Description
Have you saved lots of articles but still struggle to find the key points at a glance? Give it an article, note, or clearly defined topic that you have permission to use. It will organize the information around one question and present it as a hand-drawn-style diagram. The first version focuses on method steps and operational workflows. You’ll get: ① A knowledge diagram with clear steps, conditions, and reading order. ② Copyable text, including the title, nodes, and key explanations. ③ A source checklist that preserves the original evidence and items requiring confirmation. ④ Short sharing copy to make it easy to post with the image. It won’t depict parallel content as causal, omit key conditions, or invent performance data. When there is too much content, it will narrow the topic first while preserving readable type size and whitespace for mobile viewing. Creating the final image requires access to an image or drawing tool in the current environment. If no tool is available, it will clearly state that the image has not been generated and preserve the complete image-ready draft. Image-generation usage is subject to the platform’s rules at the time. Suitable for study organization, knowledge sharing, and adapting content for social media. It does not publish on your behalf or guarantee traffic. The sample image uses a newly created article and local drawing tools; it is not a YouMind runtime screenshot.
Why we love this skill
Turns complex articles into mobile-friendly hand-drawn knowledge maps, especially for methods, workflows, and branching conditions, while checking sources, numbers, and limitations.
Related Skills
View allMinimal Explainer Diagram
Turn selected text, articles, files, or project information into a clear, compact explainer diagram. It extracts key nodes and relationships to help you organize processes, hierarchies, comparisons, timelines, or connections between different approaches. It’s suited to project presentations, team communication, content summaries, and organizing ideas. You can specify the diagram type, focus, layout direction, or accent color. Or simply provide the material, and it will determine a suitable way to present the content. It supports flowcharts, structure diagrams, comparison diagrams, timelines, and solution relationship diagrams. Before drawing, it lets you confirm the diagram type, layout, and colors to help prevent misunderstandings about the information’s focus. The finished diagram uses a white background, generous whitespace, fine lines, and flat geometric shapes, with a single low-saturation accent color. Short node labels and clear connecting lines show the relationships. It doesn’t crowd the original text or add people and decorative illustrations, so readers can quickly understand the content structure without first reading lengthy explanations.
 Image
Stick Figure Explainer
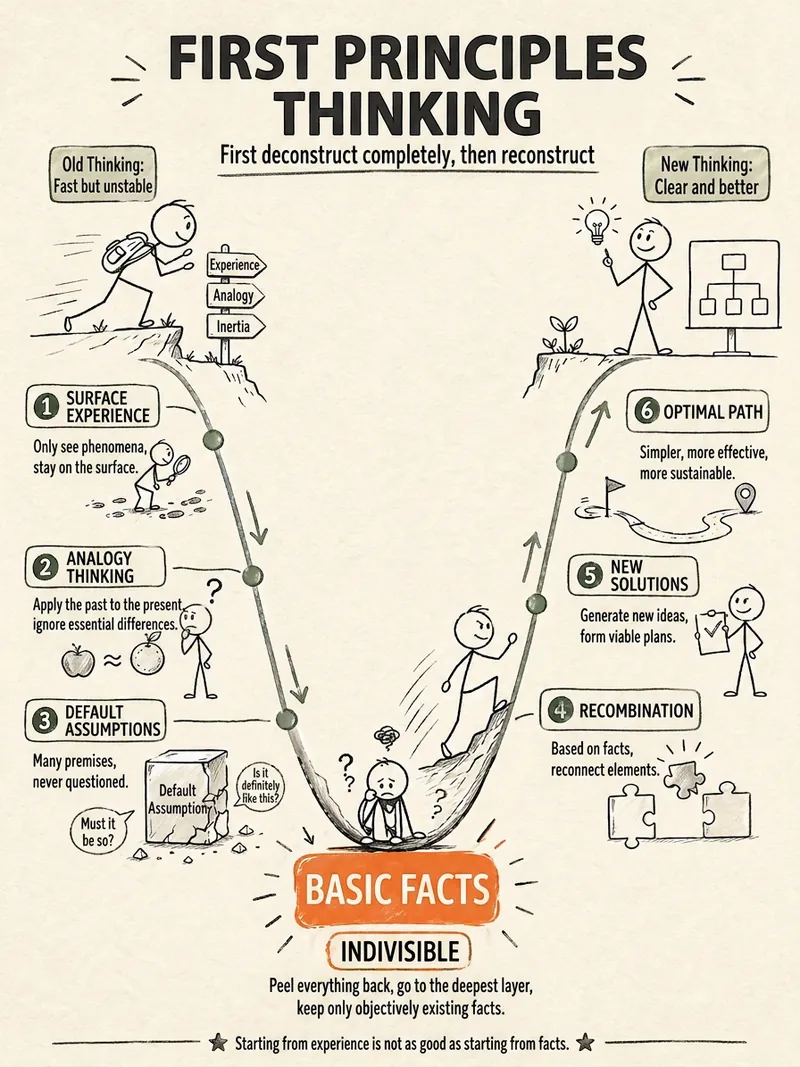
Turn complex concepts, abstract theories, lengthy processes, notes, business analyses, or growth stories into prompts for vertical knowledge cards, infographics, and hand-drawn explainers optimized for GPT-Image 2. Whether you’re organizing a process, comparing before and after, analyzing causes, categorizing knowledge, or telling a story of growth from a low point to a breakthrough, it distills the key takeaway and matches it with a suitable composition, visual metaphor, and reading flow—making the content easier to understand and remember at a glance. You’ll receive a Chinese card structure guide and visual system recommendations covering composition, hand-drawn style, color philosophy, and typographic character, along with a ready-to-copy English image-generation Prompt. The default canvas is a 3:4 vertical format, suitable for knowledge cards, Xiaohongshu cards, vertical infographics, and posters. Depending on the topic, stick figures, simplified characters, or icons can be used to show states, actions, and emotions, while keeping the number of information modules under control to avoid crowded visuals, text that is too small, or scattered emphasis. It’s ideal for quickly turning reading notes, frameworks, workplace skills, psychology and personal growth topics, business insights, product workflows, and complex concepts into clear, narrative-driven, actionable visual content.
IP Hand-Drawn Visual Consultant
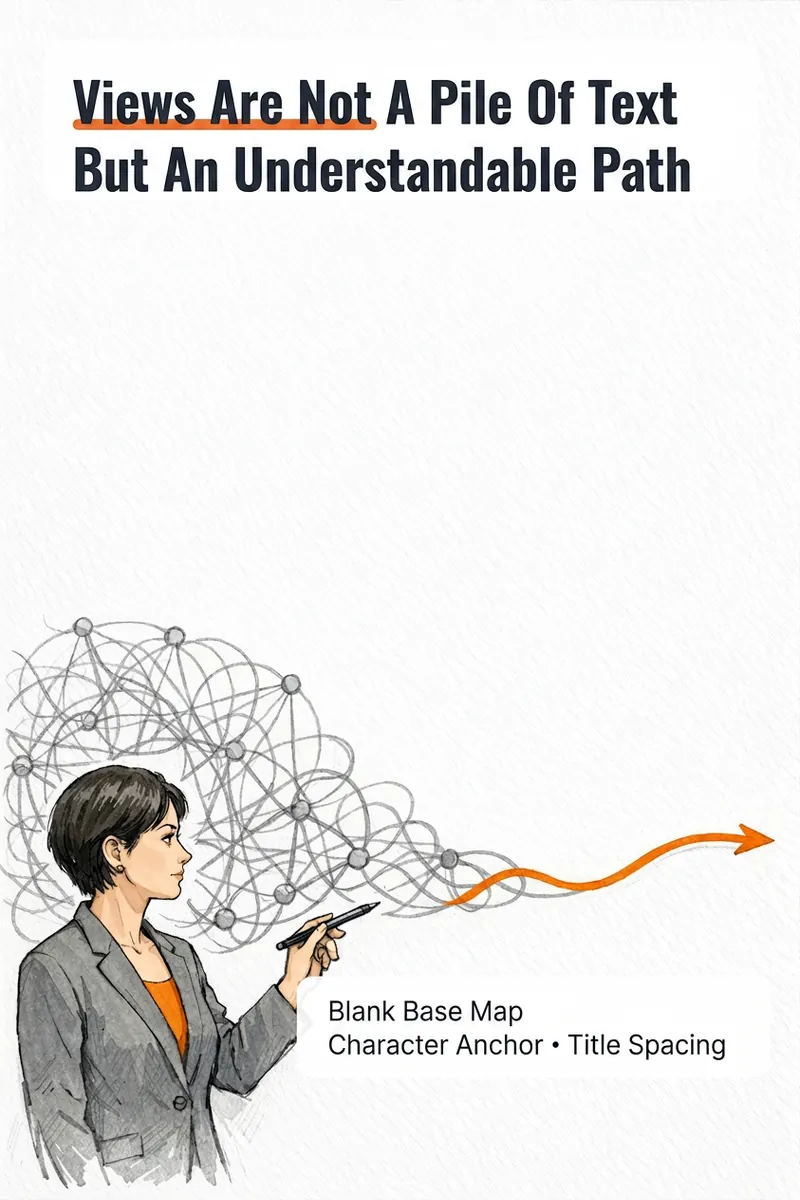
It's not that you can't write content; you often get stuck at the last step: what kind of image should this idea, method, or story become to feel like you? The IP Hand-Drawn Visual Consultant breaks down your content expression into a suitable visual form, then gives you a practical visual + text solution. You will receive: - A judgment of whether the content suits an opinion diagram, method diagram, or story diagram; - A hand-drawn visual direction that matches your field and style; - A copy confirmation form to lock in text after review; - A hand-drawn visual base map without text, or a ready-to-use text-free image prompt; - A layout guide: where to place titles, steps, and key text, and how much space to leave. Why provide a text-free base map first? Chinese text needs to be accurate and editable. Instead of letting the image generation model randomly 'draw' text, we first design the image, characters, or scene with white space for text, and then you overlay the confirmed copy using your familiar tools. This is suitable for those who want to first verify if they need a personal visual expression: consultants, lecturers, coaches, knowledge content creators, or those just starting to build their personal brand. This skill currently can do: a single, single-platform content visual solution; one text-free preview base map or text-free prompt; copy confirmation and layout guide; extract hand-drawn IP anchors from photos if available; use professional props, scenes, or abstract symbols to build recognition without photos. Currently does not: generate multiple images or content card sets at once; adapt to multiple platforms simultaneously; save IP archives across tasks; directly generate publishable final images with accurate Chinese text; auto-publish to any platform. If after the experience you naturally need multi-image, multi-platform, long-term fixed character images or serialized columns, those are scenarios better addressed by the subsequent Pro and Max versions. This skill will first complete this single experience and will not proactively upsell.
Information
- Version
- v6
- Last updated
- Runtime credits
- Usage-based
- Models
- Auto